- Use combinations of stable identifiers and context rather than treating one shared field as proof of identity.
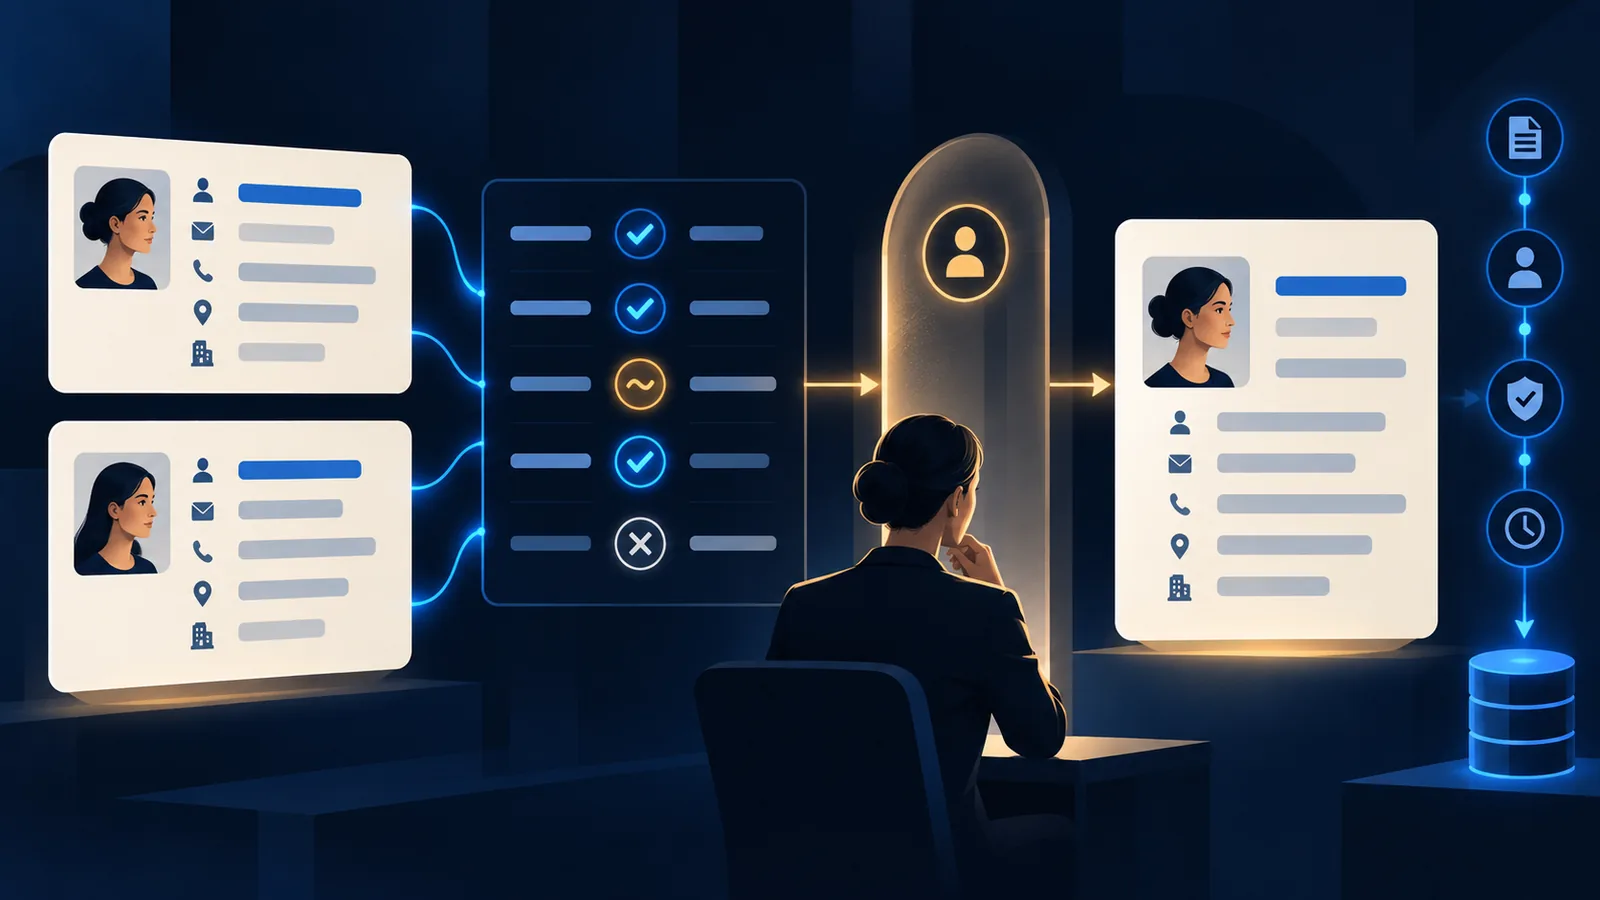
- Classify candidates as confirmed match, possible match or separate record, with review proportional to the merge consequence.
- Preserve field provenance, activities, relationships and the merge decision; then fix the intake source that created the duplicate.
Why duplicate records are operationally dangerous
Two records for one customer split conversation history, consent context, ownership and opportunity information. One record may receive follow-up while the other contains the reply. A report may count two leads, and an automation may send conflicting messages.
The reverse mistake is also harmful: merging two legitimate people or organizations because they share a domain, phone number or address. The objective is not one record at any cost. It is one trustworthy identity for each real entity, with relationships represented deliberately.
Duplicate control is one part of a complete CRM data quality operating model.
Define the identity you are matching
Decide whether the object represents a person, company, location, household, opportunity or inquiry. A person can have several email addresses, a company can have several locations and two opportunities can involve the same account without being duplicates.
List the identifiers that are stable enough for each object and the relationships that must remain separate. Include external system IDs where available, but do not assume an imported ID proves the CRM records describe the same real-world entity.
Person
Email, phone, name, account relationship and source context considered together.
Organization
Legal or operating name, domain, address, registration identifiers and parent-child structure.
Opportunity
Account, request, product or service scope, time period and commercial intent.
Inquiry
Original submission, channel, timestamp and the customer need that triggered the record.
Create matching tiers instead of one aggressive rule
Begin with normalized comparisons: lowercase email where appropriate, canonical phone format, trimmed names and approved company-name transformations. Keep the original values as source evidence. Normalization helps comparison; it should not silently rewrite every displayed value.
Use exact rules for strong identifiers and weighted or fuzzy rules for candidates. A shared email may be a strong person signal but is not universal. A shared domain may suggest the same company while still requiring location or legal-entity review.
Confirmed match
Evidence is strong enough for an approved automatic or streamlined resolution path.
Possible match
The records are similar, but conflicting or incomplete evidence requires a person to decide.
Separate records
The similarity is explained by a valid relationship, shared contact detail or common organization.
Insufficient evidence
The workflow waits, enriches from an approved source or leaves the records unchanged.
Give reviewers the evidence needed to decide
A reviewer should see why the records matched, conflicting field values, account and opportunity relationships, recent activities, owners, consent or preference information, external IDs and what would happen to dependent records. Showing two names side by side is not enough.
Use human-in-the-loop automation for ambiguous matches where the consequence of a bad merge exceeds the value of speed. Capture the decision and reason so matching rules can improve from actual cases.
Design the merge as a controlled business transaction
Select a surviving record according to explicit rules, not simply the newest or most complete record. Choose field values based on source authority and verification date. Reattach activities and relationships carefully, retain old identifiers where useful and make the retired record traceable to the survivor.
Before committing, preview the result and identify automations that a merge may trigger. Afterward, confirm ownership, open work, communication preferences, opportunity links, reporting and connected-system synchronization. Record the source records, selected values, reviewer and time.
When recurring updates and matching controls need to be implemented across systems, OpSmith's CRM data-entry automation service focuses on preserving trustworthy context rather than copying every value automatically.
Prevent duplicates at creation and update
Search before creating a record at forms, imports, integrations and manual entry. Where the evidence indicates an existing record, update only fields the source is allowed to change. Where the evidence is ambiguous, create a review task or staging record instead of a production duplicate.
Make retries idempotent by storing the source event or request identifier. Otherwise, a timeout can cause a form or integration to submit the same request twice. Test matching rules separately for new records, edits, bulk imports and API integrations because product behaviour can differ by path.
Measure the duplicate system, not just the duplicate backlog
Track candidates created by source, confirmed-match rate, false-positive rate, review age, merge reversals and repeat creation after a merge. A shrinking backlog can hide a bad rule if reviewers are merging legitimate records to meet a target.
Review false positives and false negatives together. A strict rule may avoid bad merges while allowing duplicates through; a broad rule may catch more candidates while overwhelming reviewers. Adjust thresholds from representative cases and business consequences.
Frequently asked questions
What causes duplicate records in a CRM?
Common causes include separate forms and integrations, bulk imports without stable identifiers, users creating before searching, retries after uncertain API responses and matching rules that do not cover every record-entry path.
Is an identical email address enough to merge CRM records?
Not always. Shared inboxes, reused addresses, aliases and data-entry errors can create false matches. Consider the object type, other identifiers, relationships and conflicting evidence before merging.
Should duplicate CRM records be deleted or merged?
A controlled merge is often preferable when one real entity is represented twice because useful activities and relationships can be preserved. Deletion may be appropriate in limited cases, but it should follow retention and audit requirements.
Can AI identify CRM duplicates?
AI or probabilistic matching can propose candidates, particularly when names and addresses vary. It should expose the evidence and confidence, while consequential or ambiguous matches follow an approved review path.
How can duplicate records be prevented from returning?
Apply matching before creation across every intake channel, use stable source identifiers, make integration retries idempotent and monitor duplicate candidates by their source.
Sources and further guidance
These official references provide relevant technical, privacy, risk-management or accountability guidance. OpSmith applies the useful principles to the operation of one business workflow.
- Use Microsoft Dataverse to detect duplicate records and mergeMicrosoft Learn
- Things to know about matching rulesSalesforce Help